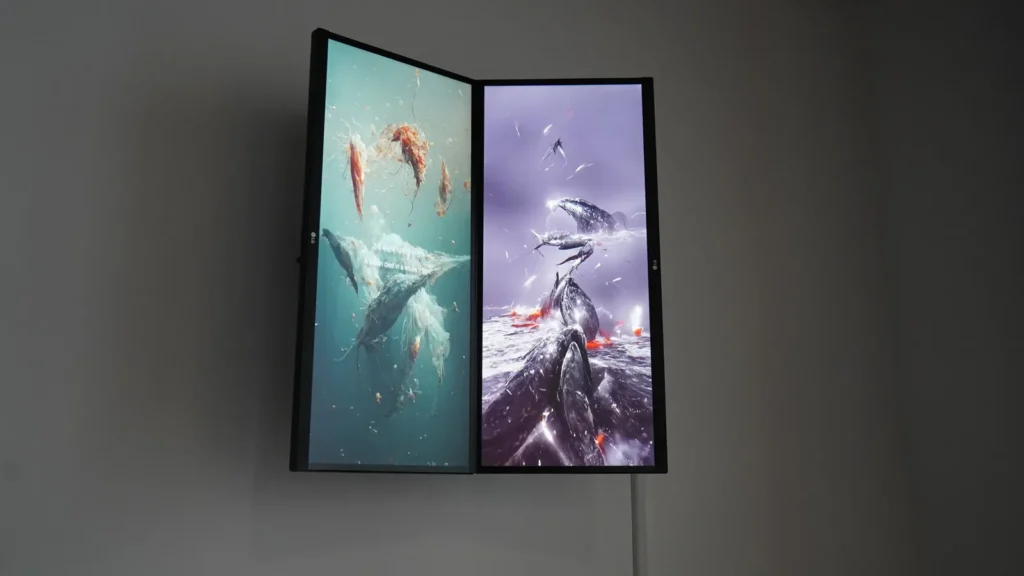
속담은 오래전부터 인간 사회에서 널리 말하여 져서 굳어진 어구들이다. 이는 공동체의 의식 구조를 반영하기 때문에 언어학이나 문화인류학 등에서 연구 대상으로 많이 삼고 있다. 이와 같은 속담을 인공지능이 이미지와 영상으로 구현한다.
이 시도는 인공지능의 기능으로 가장 인간적인 특징인 언어의 사용에 대하여 탐색하는 연구이다.
총 66개의 어구를 한국에서 통용되는 문구들 33개와 영미권에서 통용되는 문구를 33개의 문구들을 텍스트 프롬프트로 변환하여, 딥러닝 중 Text to Image 기반의 프롬프트 엔지니어링 (disco diffusion v5, midjourney)으로 구성하였다.
신경망의 작용을 거치는 프로세스를 통해 구성되며, 각 문장 속 텍스트를 근간으로 데이터를 구성하여 영상으로 생성해낸다. 음악의 경우도 동일 데이터를 파라미터로 적용하며, 인공지능 알고리즘 기반의 사운드 생성기로 제작한다.
Proverbs are phrases that have been widely spoken in human societies for a long time and have become ingrained. They reflect the consciousness structure of a community and are therefore a popular subject of research in linguistics and cultural anthropology. A.I. can translate these proverbs into images and videos. This study explores the use of language, one of the most human characteristics, as a function of AI.
A total of 66 phrases, 33 phrases commonly used in S.
Korea and 33 phrases commonly used in the English-speaking world, were converted into text prompts and configured as Text to Image based prompt engineering (disco diffusion v5, midjourney) during deep learning.
It is constructed through a process that goes through the action of an artificial neural network, which organizes data based on the text in each sentence and creates a video. In the case of music, the same data is applied as a parameter, and it is produced with a sound generator based on artificial intelligence algorithms.
+
소장 : 사단법인 캔파운데이션 / 2022년 / 서울/ 한국
Collection :
CAN Foundation (incorporated association)/ 2022 / Seoul / Korea